
Today
Manual, periodic, trapped in a deck.
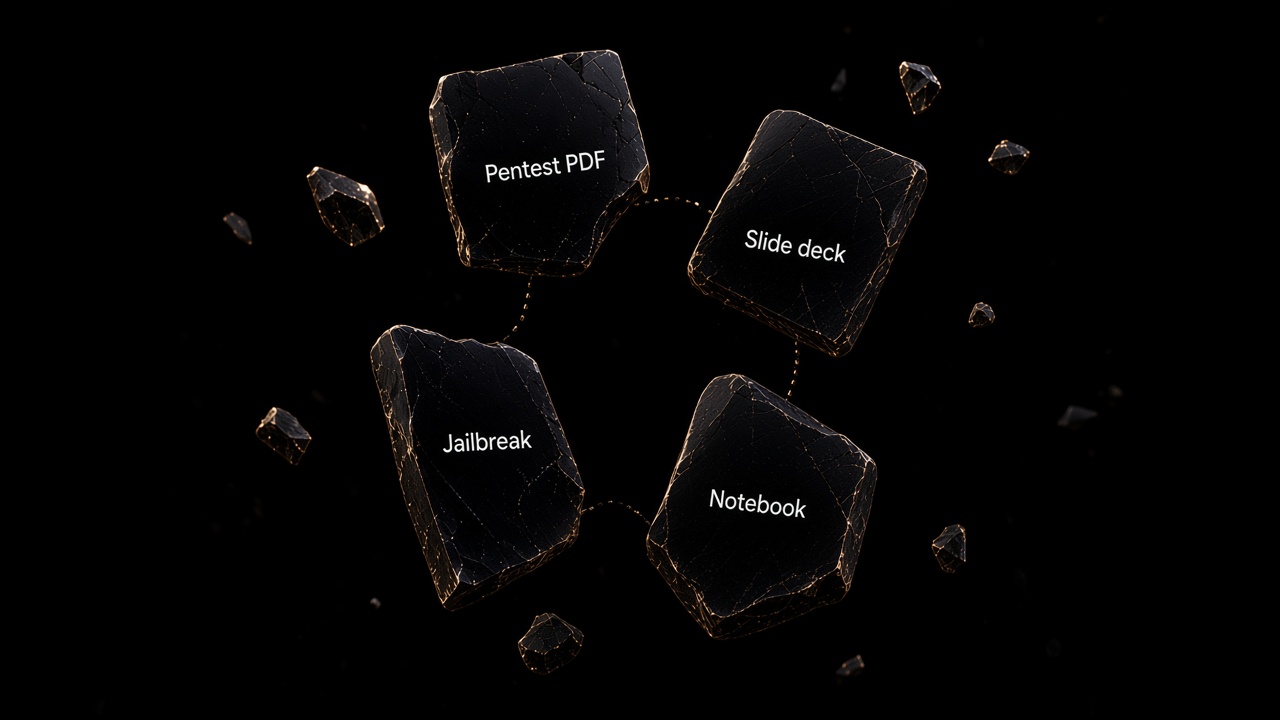
Testing is manual, periodic, and trapped in slide decks. Nothing regresses the last jailbreak after the next model bump.
- Manual
- Periodic
- Slide deck
- Stale
Agentic Red Teaming
Find weaknesses before attackers do.
Simulate real-world attacks against your AI agents to uncover security vulnerabilities, unsafe behaviors, and data exposure risks. Get actionable findings and evidence to strengthen your defenses.
 ScoutClaude
 PlannerOpenAI
01 Brief · Orchestrator
Start campaign 14. Probe the support graph.
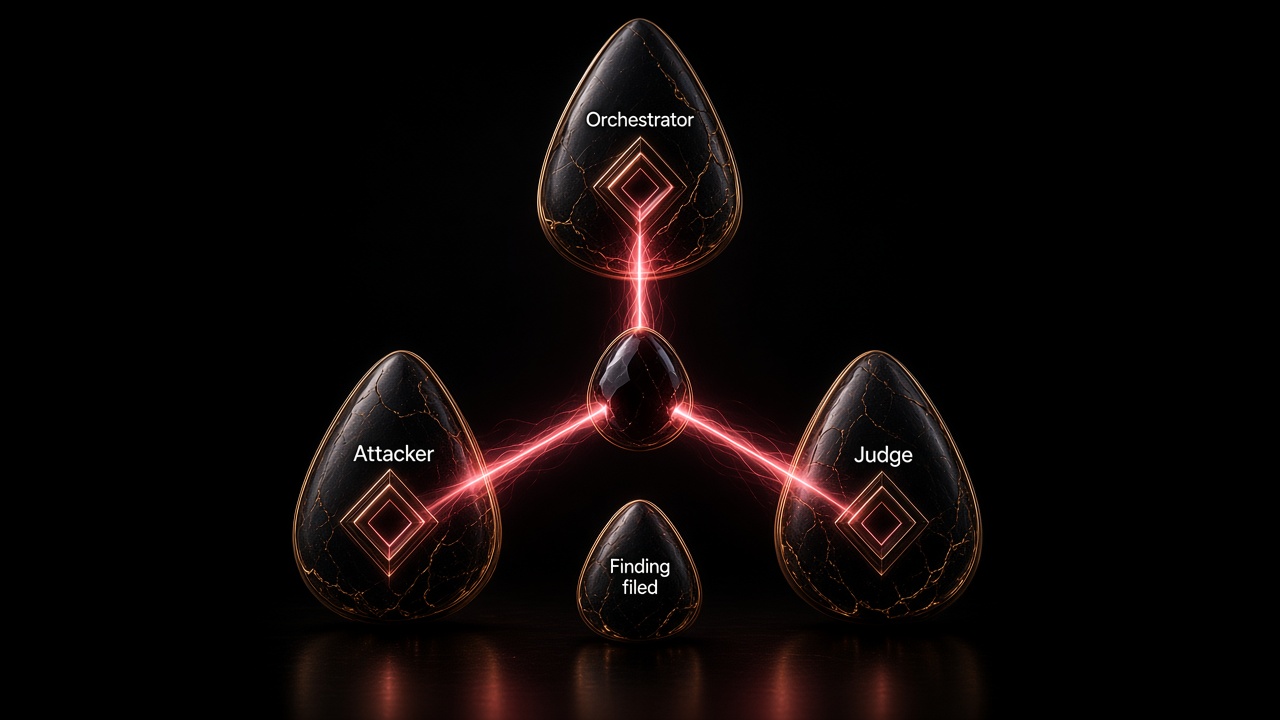
Orchestrator
Sets the campaign
Attacker
Probes the agent
Judge
Scores what landed
Evidence
Filed, not a deck
Simulate real-world attacks against your AI agents to uncover security vulnerabilities, unsafe behaviors, and data exposure risks. Get actionable findings and evidence to strengthen your defenses.
Three roles, one workflow, not a pile of prompts in a notebook.
Scheduled and on-demand campaigns against production-shaped targets.
Triage, severity, and owners instead of a dumped JSON report.
Findings write into compliance. That is the point of a control layer.
A finding in a deck is not a campaign.
Today
Testing is manual, periodic, and trapped in slide decks. Nothing regresses the last jailbreak after the next model bump.
With Zenjin
Continuous workflows with an orchestrator, attacker, and judge. Findings review and compliance mapping in the same system.
From a named target to a finding that still holds after the next bump.
01
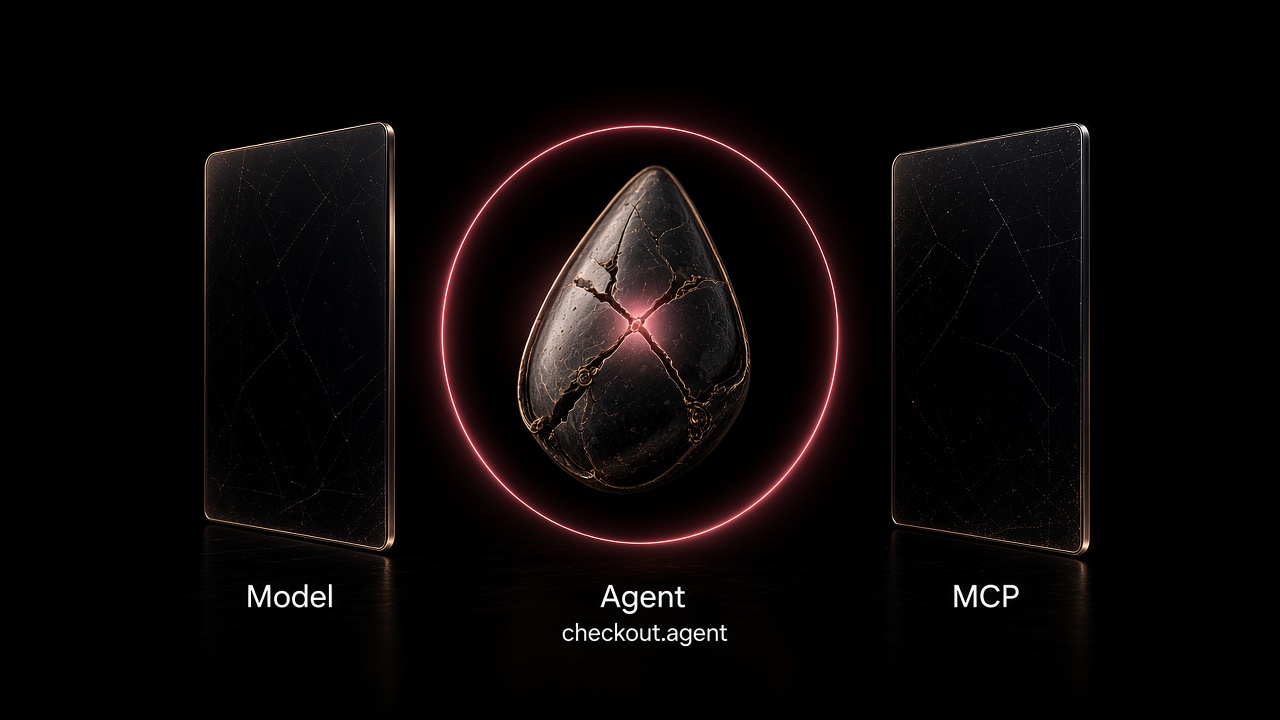
Point the workflow at a model, agent, or MCP in inventory.
02
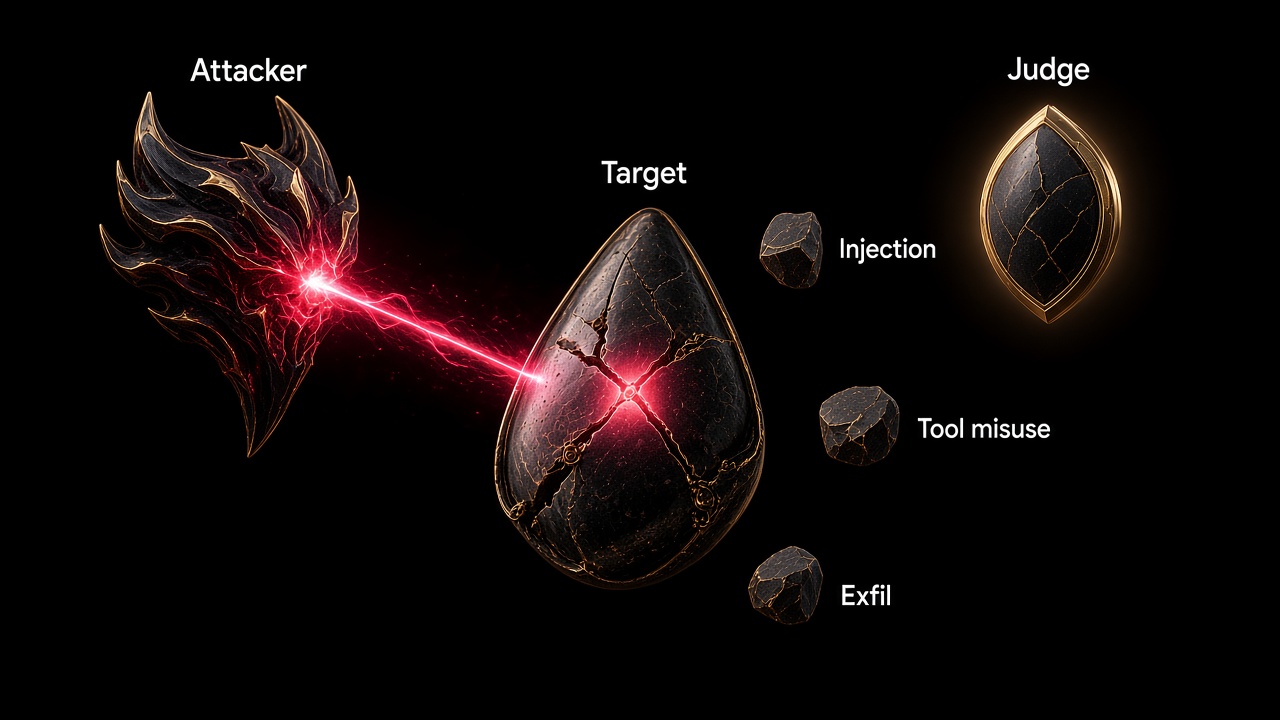
Automated campaigns: injection, tool misuse, exfil, system-prompt exposure.
03
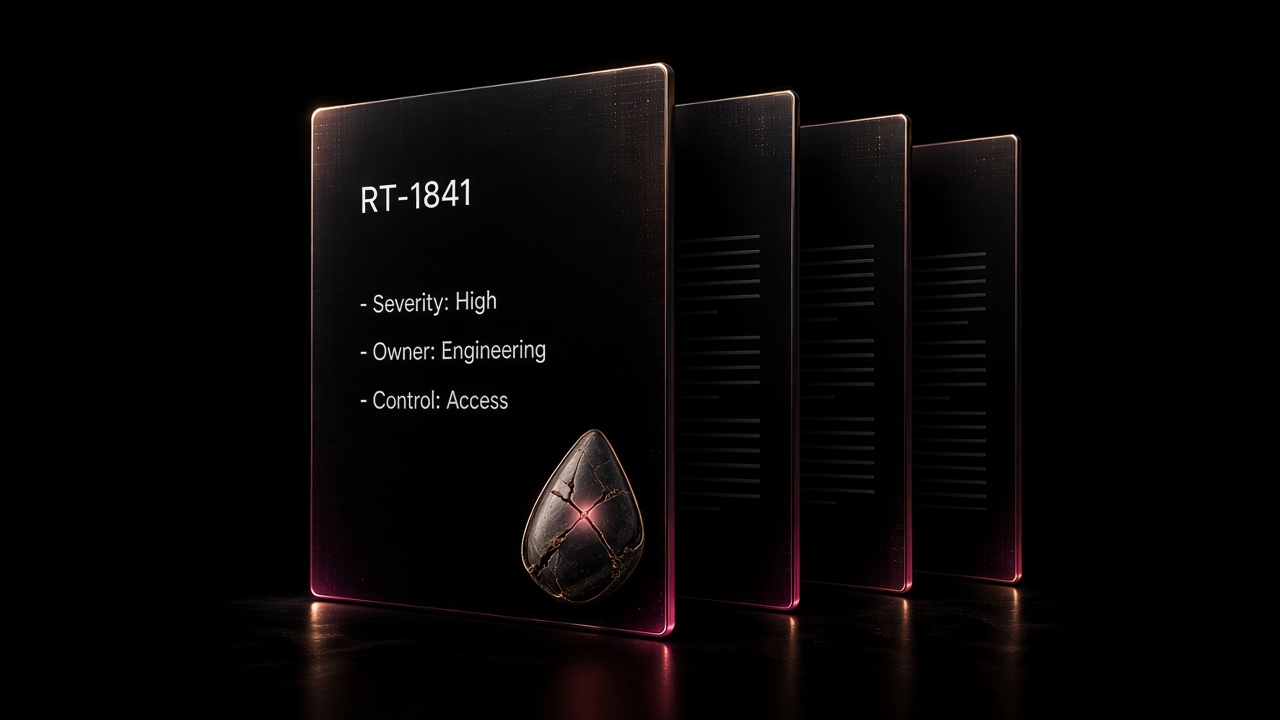
Severity, reproduction, and owners, then map into controls.
04
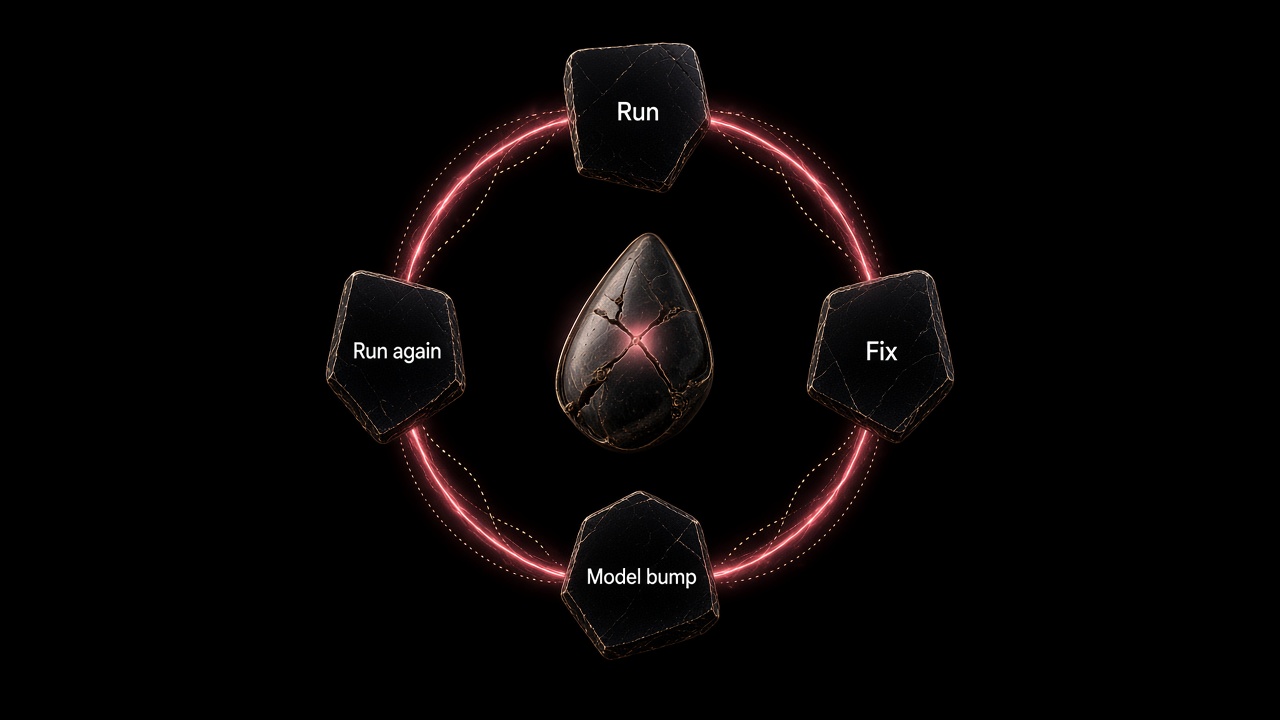
Cadence tests so the last fix still holds after the next prompt or model change.
Those are scanners or engagements. Zenjin agentic red teaming is a product workflow whose output is inventory-aware findings that become audit evidence.
Both. Tool misuse and MCP paths are first-class, not an afterthought on a chat completion.
This is the continuous automated layer. Human engagements still matter for novel chains; we keep the known attacks from regressing.
Attacker agents run against your agents, with an orchestrator setting the campaign and a judge scoring whether a leak, injection, or tool misuse actually landed.
Yes. Severity, reproduction, and owners write into the same evidence trail as Data Security Posture Management and evals.
Prompt injection, tool misuse, exfiltration, and system-prompt exposure, against models, agents, and MCP targets already in inventory.